Posts

Segment Anything in High Quality #1160

Image
Segment Anything in High Quality #1160 Source

Nearly 4,000 people working in tech lost their jobs because of AI in May #1159

Image
Nearly 4,000 people working in tech lost their jobs because of AI in May #1159 Source  

StyleDrop - It allows a user to generate new images that follow a specific style of their choice given only a single style reference image #1158

Image
StyleDrop - It allows a user to generate new images that follow a specific style of their choice given only a single style reference image #1158 Source

Humans in 4D: Reconstructing and Tracking Humans with Transformers #1157

Image
Humans in 4D: Reconstructing and Tracking Humans with Transformers #1157 Source

LLaMa-Adapter Multimodal #1156

Image
LLaMa-Adapter Multimodal #1156 Source

Diffusion Self-Guidance for Controllable Image Generation #1155

Image
Diffusion Self-Guidance for Controllable Image Generation #1155 Source

Bytes Are All You Need: Transformers Operating Directly On File Bytes #1154

Image
Bytes Are All You Need: Transformers Operating Directly On File Bytes #1154 Source  

SnapFusion: Text-to-Image Diffusion Model on Mobile Devices within Two Seconds #1153

Image
SnapFusion: Text-to-Image Diffusion Model on Mobile Devices within Two Seconds #1153 Source

Article: ChatGPT took their jobs. Now they walk dogs and fix air conditioners #1152

Image
ChatGPT took their jobs. Now they walk dogs and fix air conditioners #1152 Source  

AVFormer: Injecting vision into frozen speech models for zero-shot AV-ASR #1151

Image
AVFormer: Injecting vision into frozen speech models for zero-shot AV-ASR #1151 Source

Nvidia: Introducing Neuralangelo - A new AI model to turn 2D video from any device -- cell phone to drone capture -- into 3D structures with intricate details #1150

Image
Nvidia: Introducing Neuralangelo - A new AI model to turn 2D video from any device -- cell phone to drone capture -- into 3D structures with intricate details #1150 Source  

Meta Quest 3 officially announced by Mark Zuckerberg #1149

Image
Meta Quest 3 officially announced today by Mark Zuckerberg before their Meta Game Showcase. This is amazing but I doubt I'll be able to afford it anytime soon. It's releasing after September 2023 though. I may have a job, let's see. Source  

Japan Goes All In: Copyright Doesn’t Apply To AI Training #1148

Image
Japan Goes All In: Copyright Doesn’t Apply To AI Training #1148 Source  

Large sequence models for software development activities #1147

Image
Large sequence models for software development activities #1147 Source

UAE’s Falcon 40B, World’s Top-Ranked AI Model from Technology Innovation Institute is Now Royalty-free #1146

Image
UAE’s Falcon 40B, World’s Top-Ranked AI Model from Technology Innovation Institute is Now Royalty-free #1146 Source

OpenAI: We trained an AI using process supervision — rewarding the thought process rather than the outcome — to achieve new state-of-art in mathematical reasoning #1145

Image
OpenAI: We trained an AI using process supervision — rewarding the thought process rather than the outcome — to achieve new state-of-art in mathematical reasoning #1145 Source Tweet

StyleAvatar3D: Leveraging Image-Text Diffusion Models for High-Fidelity 3D Avatar Generation #1144

Image
StyleAvatar3D: Leveraging Image-Text Diffusion Models for High-Fidelity 3D Avatar Generation #1144 Source

AlteredAvatar: Stylizing Dynamic 3D Avatars with Fast Style Adaptation #1143

Image
Source

A cool AR/VR concept for the future #1142

Image
A cool AR/VR concept for the future #1142 Source Source

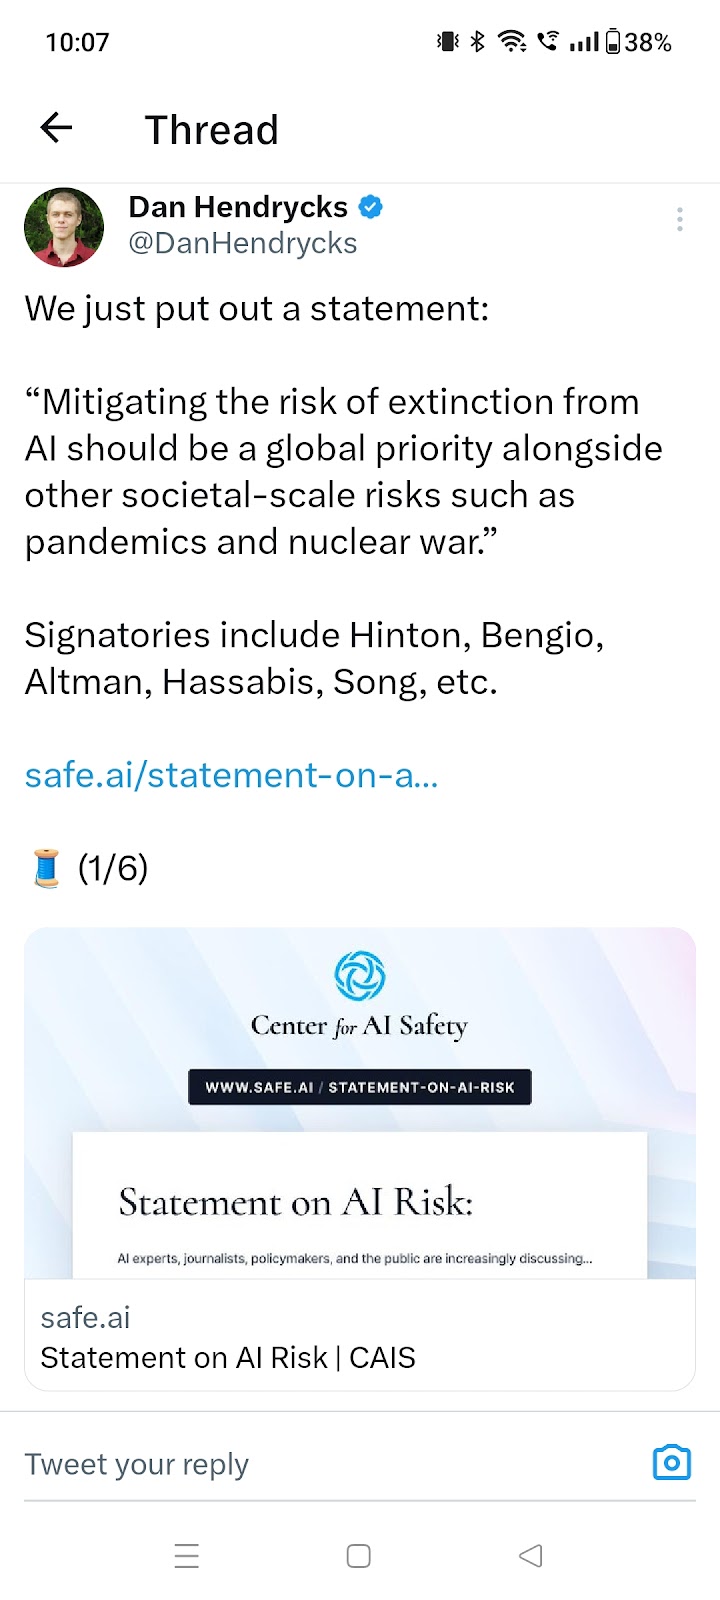
Many AI researchers and other figures sign AI statement risk #1141

Image
Many AI researchers and other figures sign AI statement risk #1141 Source  

Nvidia showcases real-time AI conversation in a game using voice #1140

Image
Nvidia showcases real-time AI conversation in a game using voice #1140 Source  

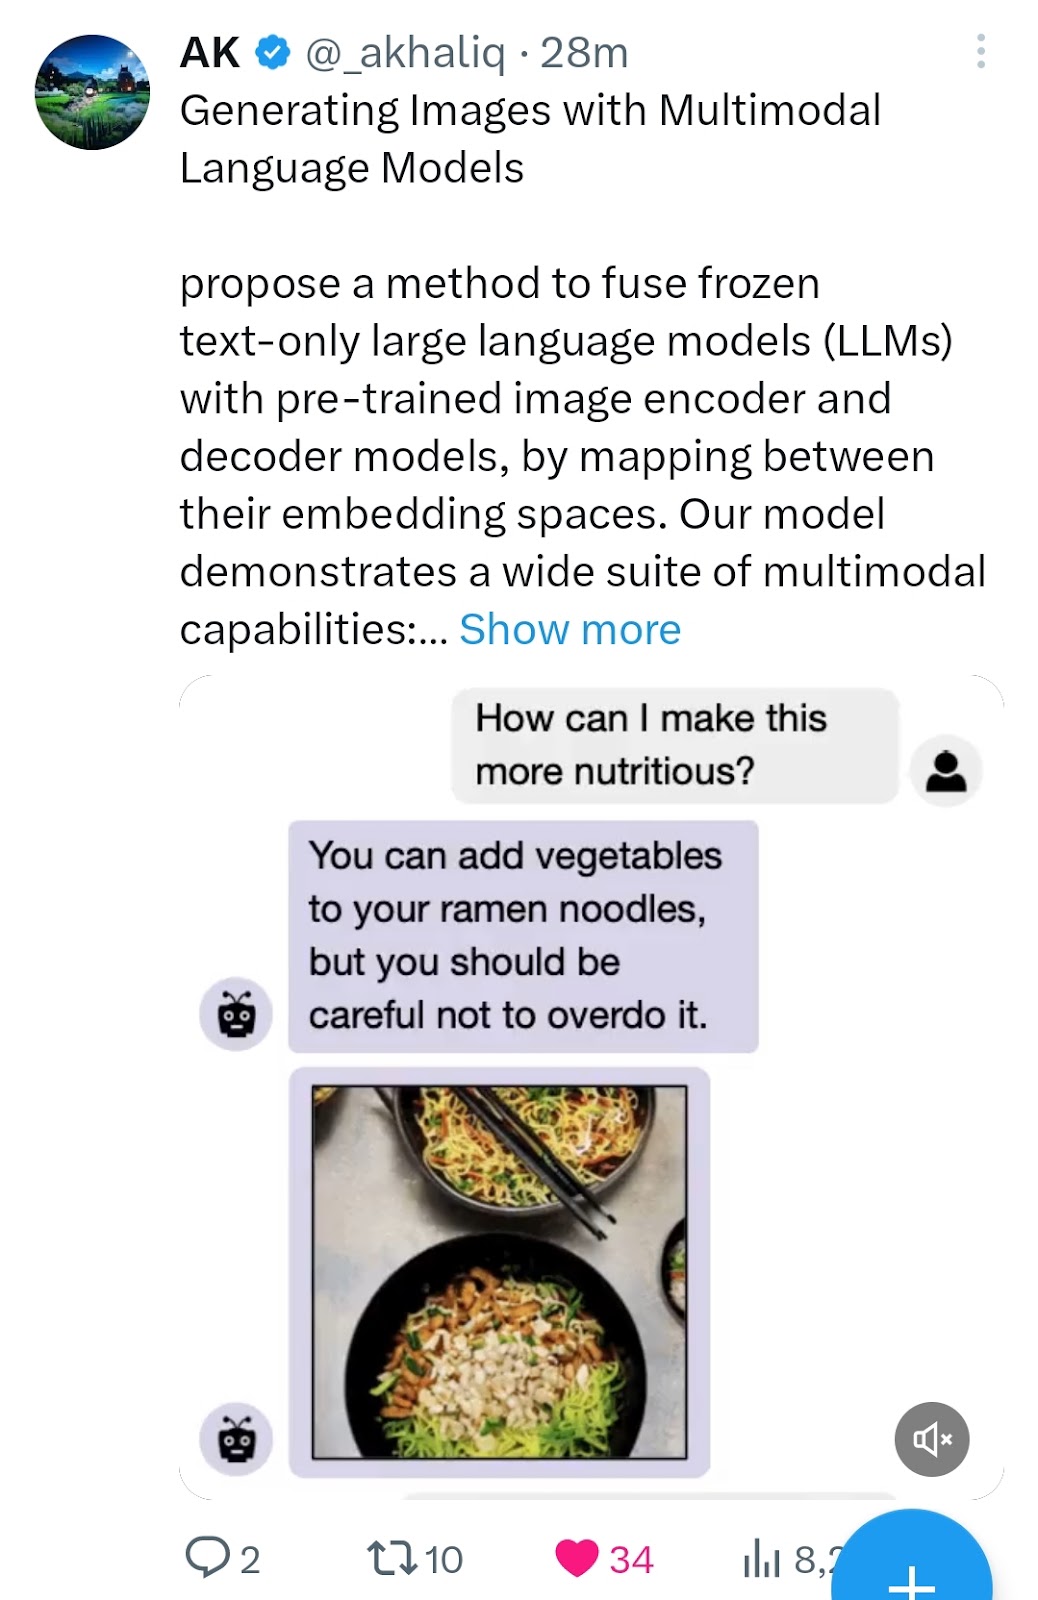
Generating Images with Multimodal Language Models #1139

Image
Generating Images with Multimodal Language Models #1139 Source  

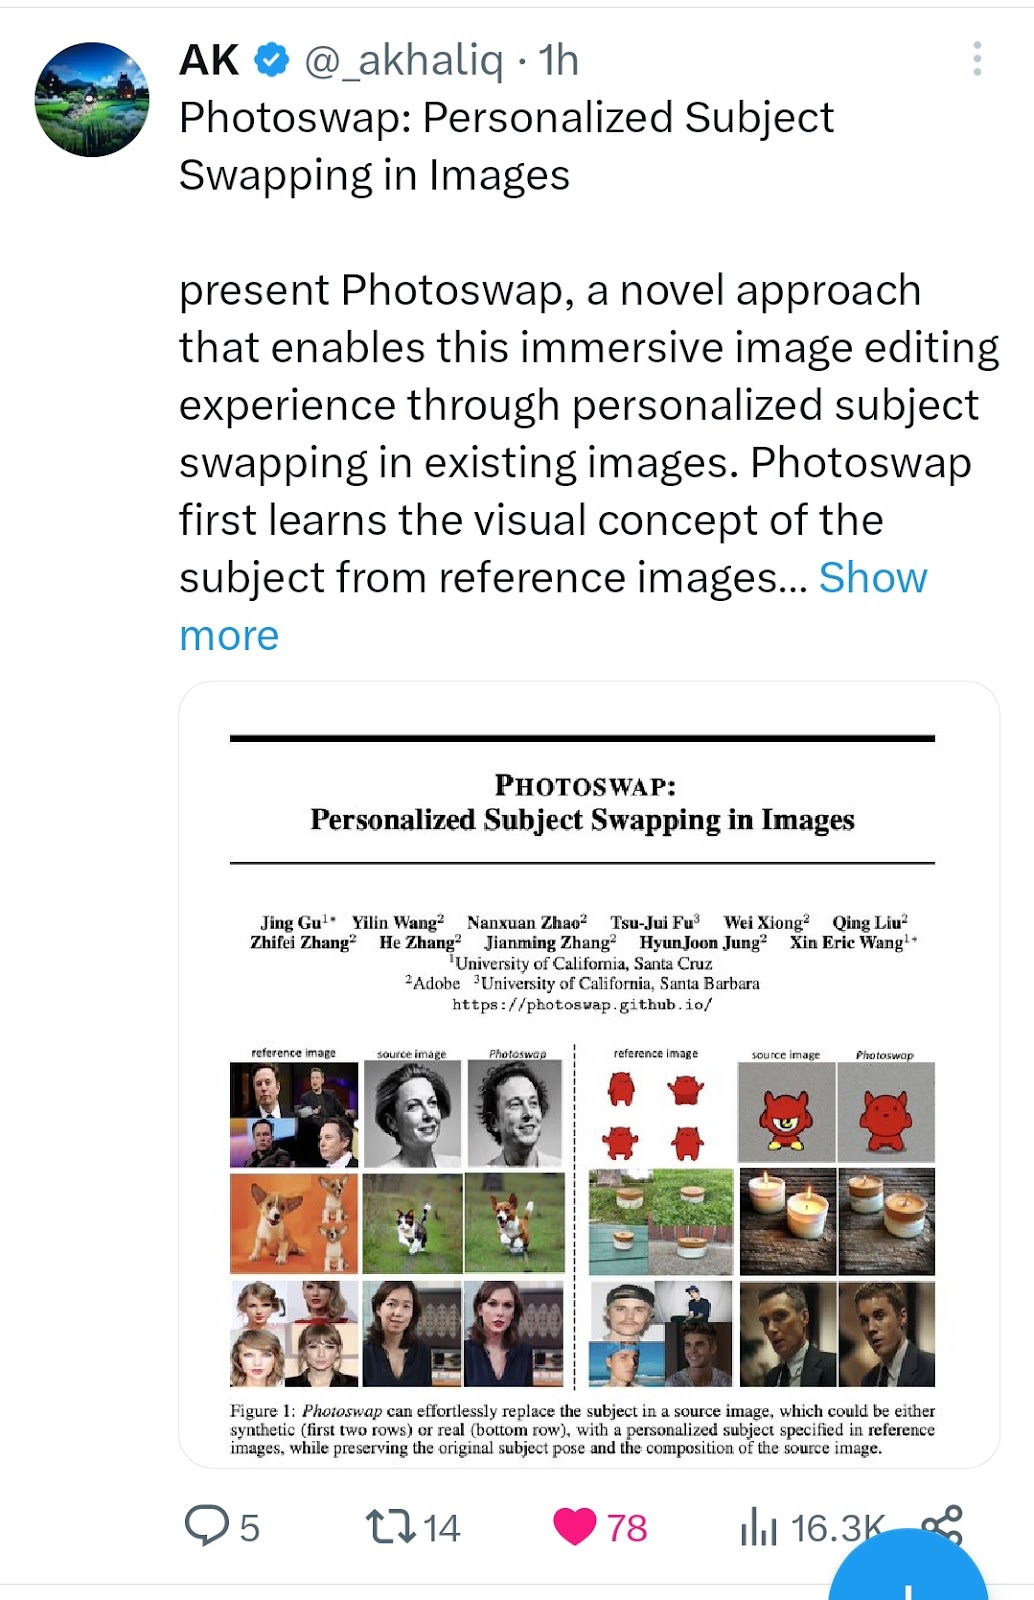
Photoswap: Personalized Subject Swapping in Images #1138

Image
Photoswap: Personalized Subject Swapping in Images #1138 Source

Break-A-Scene: Extracting Multiple Concepts from a Single Image #1137

Image
Break-A-Scene: Extracting Multiple Concepts from a Single Image #1137 Source

PandaGPT: One Model To Instruction-Follow Them All #1136

Image
PandaGPT: One Model To Instruction-Follow Them All #1136 Source

Think Before You Act: Decision Transformers with Internal Working Memory #1135

Image
Think Before You Act: Decision Transformers with Internal Working Memory #1135 Source

ControlVideo: Adding Conditional Control for One Shot Text-to-Video Editing #1134

Image
ControlVideo: Adding Conditional Control for One Shot Text-to-Video Editing #1134 Source

A Neural Space-Time Representation for Text-to-Image Personalization (similar to Dreambooth) #1133

Image
A Neural Space-Time Representation for Text-to-Image Personalization (similar to Dreambooth) #1133 Source

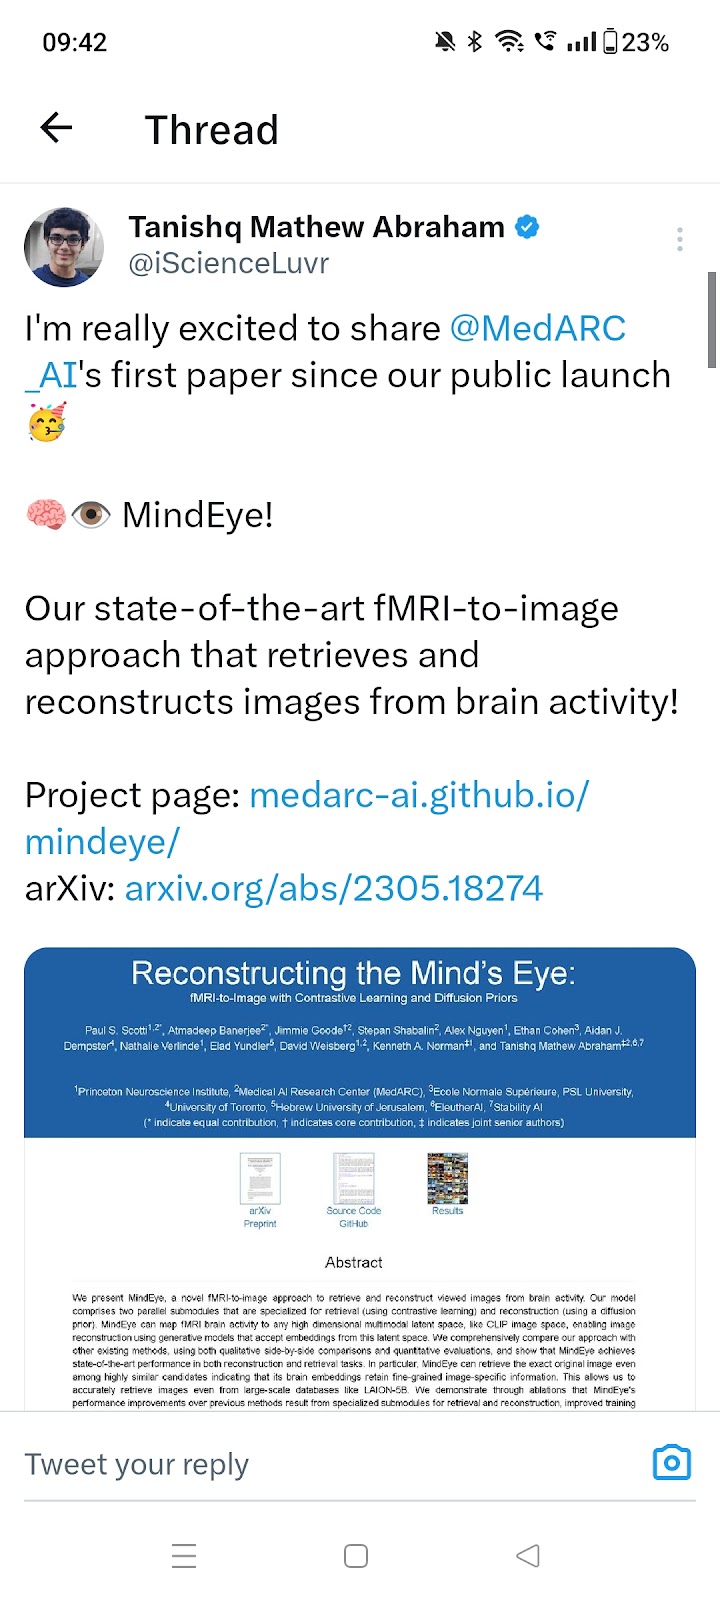
state-of-the-art fMRI-to-image approach that retrieves and reconstructs images from brain activity #1132

Image
state-of-the-art fMRI-to-image approach that retrieves and reconstructs images from brain activity #1132 Source

Voyager: An Open-Ended Embodied Agent with Large Language Models (LLM playing Minecraft) #1131

Image
Voyager: An Open-Ended Embodied Agent with Large Language Models (LLM playing Minecraft) #1131 Source

ProlificDreamer: High-Fidelity and Diverse Text-to-3D Generation with Variational Score Distillation #1130

Image
ProlificDreamer: High-Fidelity and Diverse Text-to-3D Generation with Variational Score Distillation #1130 Source

New open-source LLMs called Falcon, which comes into size 7B trained on 1.5T tokens and 40B trained on 1T Tokens #1129

Image
New open-source LLMs called Falcon, which comes into size 7B trained on 1.5T tokens and 40B trained on 1T Tokens #1129 Source

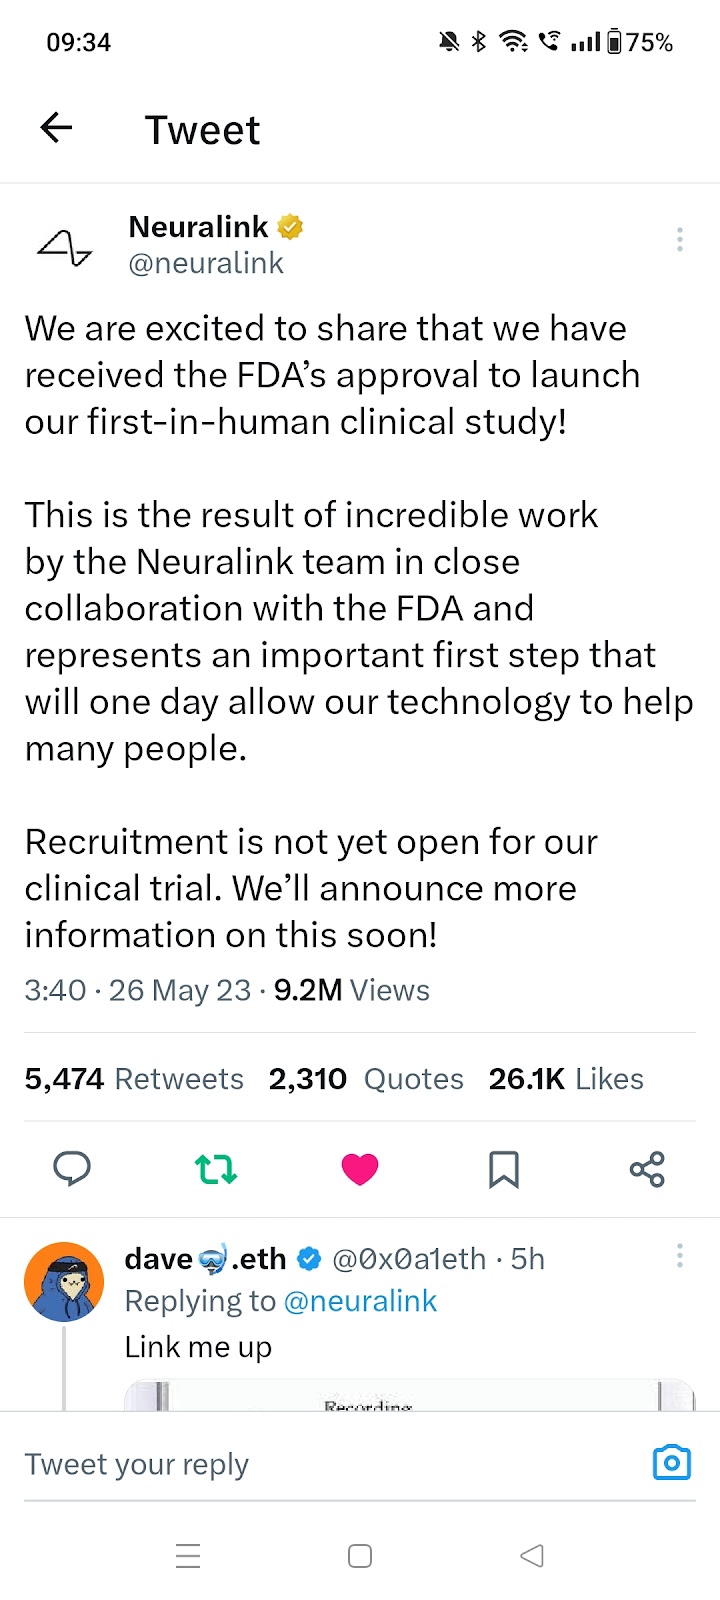
Neuralink recieved its first Human clinical trial approval from FDA #1128

Image
Neuralink recieved its first Human clinical trial approval from FDA #1128 Source  

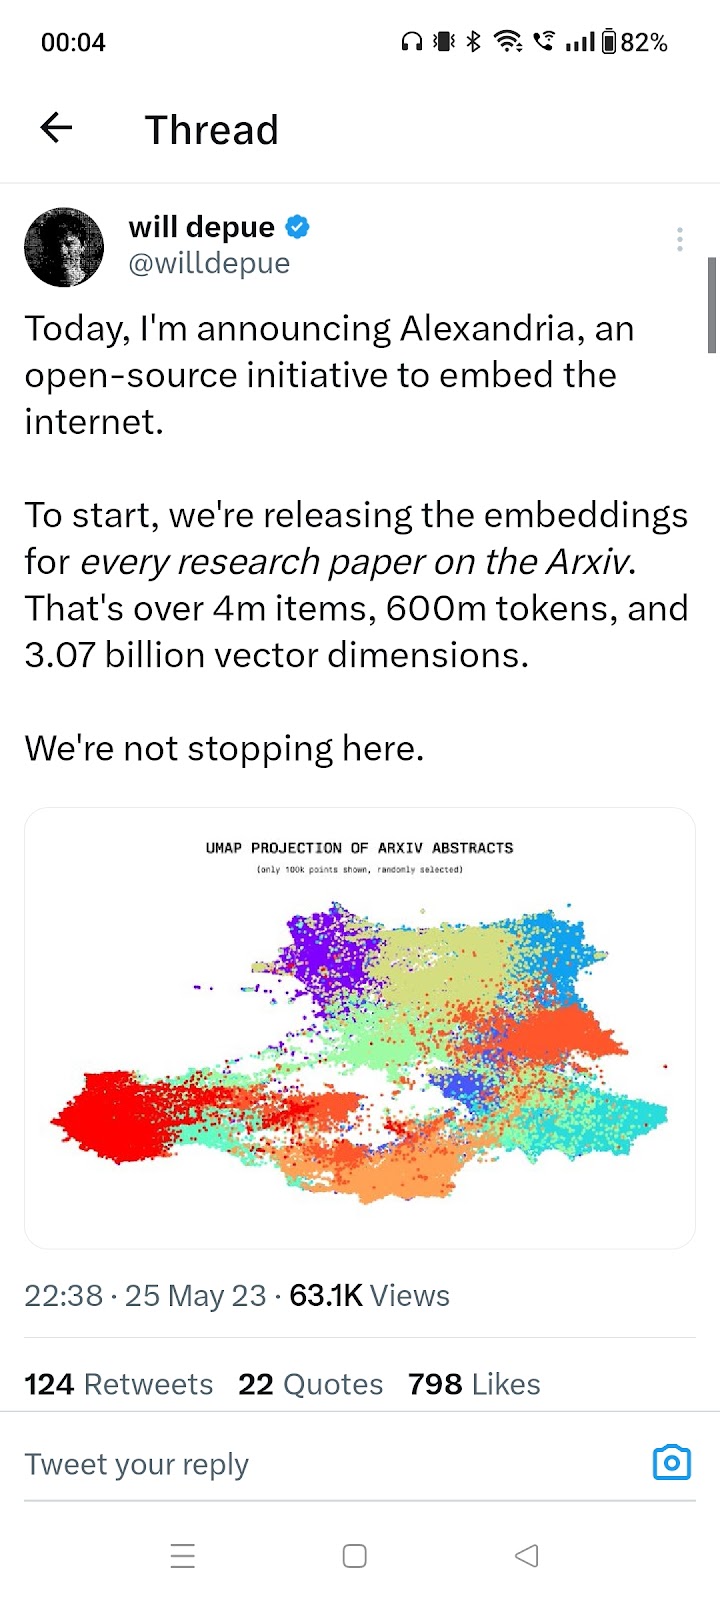
Alexandria, an open-source initiative to embed the internet, starting with Arxiv #1127

Image
Alexandria, an open-source initiative to embed the internet, starting with Arxiv #1127 Source

Stable Diffusion “Reimagine XL” model #1126

Image
Stable Diffusion “Reimagine XL” model #1126 Source  

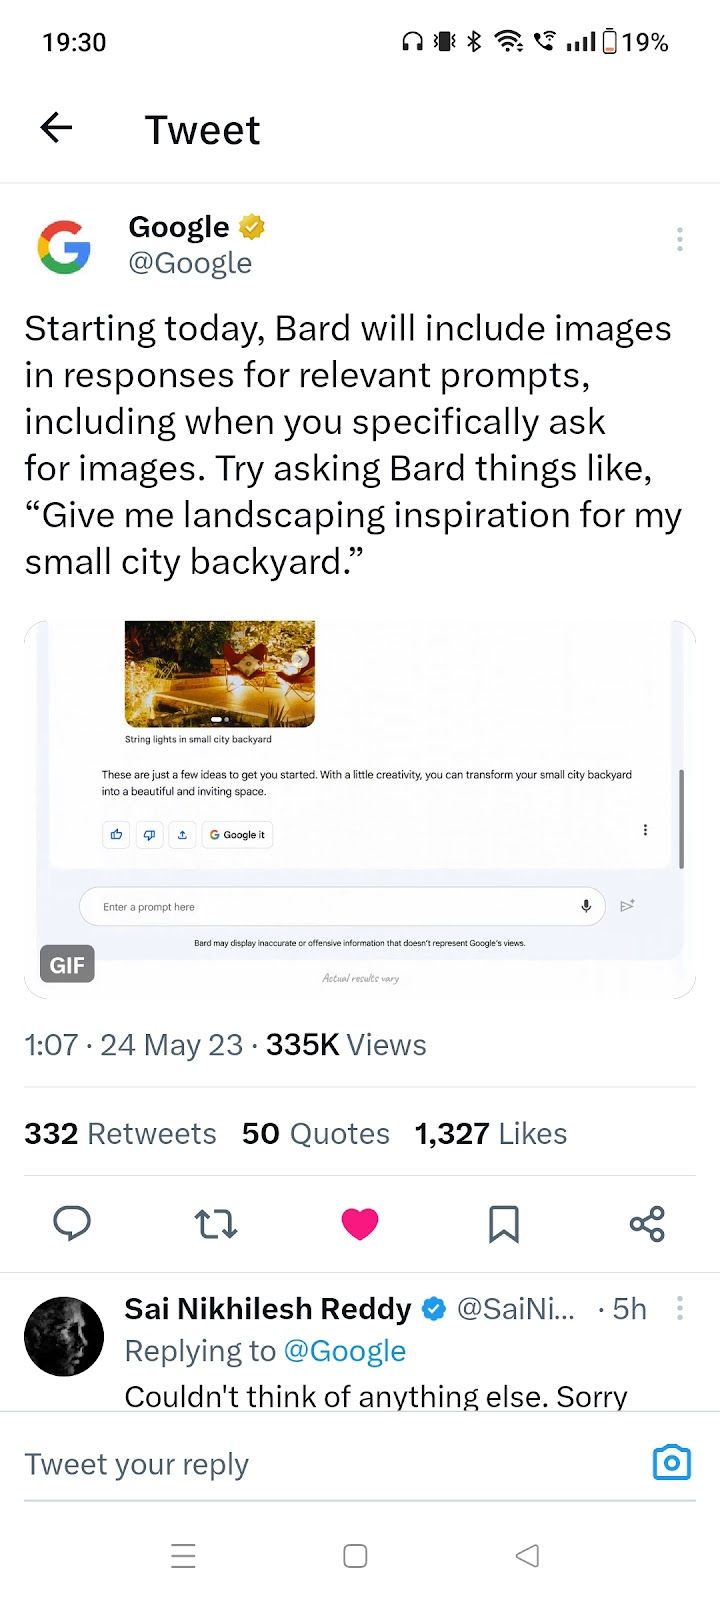
Bard will include images in responses for relevant prompts, including when you specifically ask for images #1125

Image
Bard will include images in responses for relevant prompts, including when you specifically ask for images #1125 Source

Microsoft just announced Power Virtual Agent, a new generative actions engine in its chatbot builder #1124

Image
Microsoft just announced Power Virtual Agent, a new generative actions engine in its chatbot builder #1124 Source

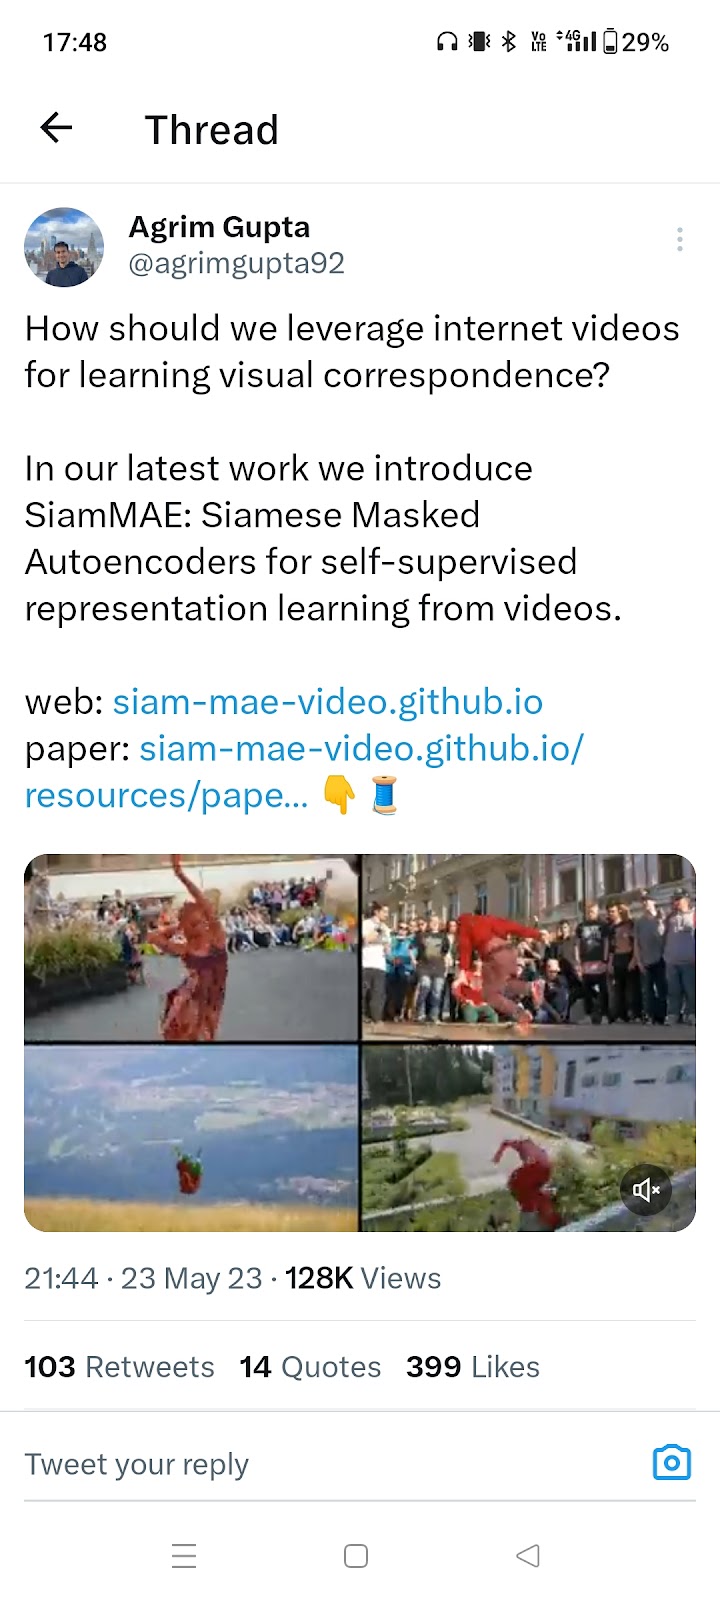
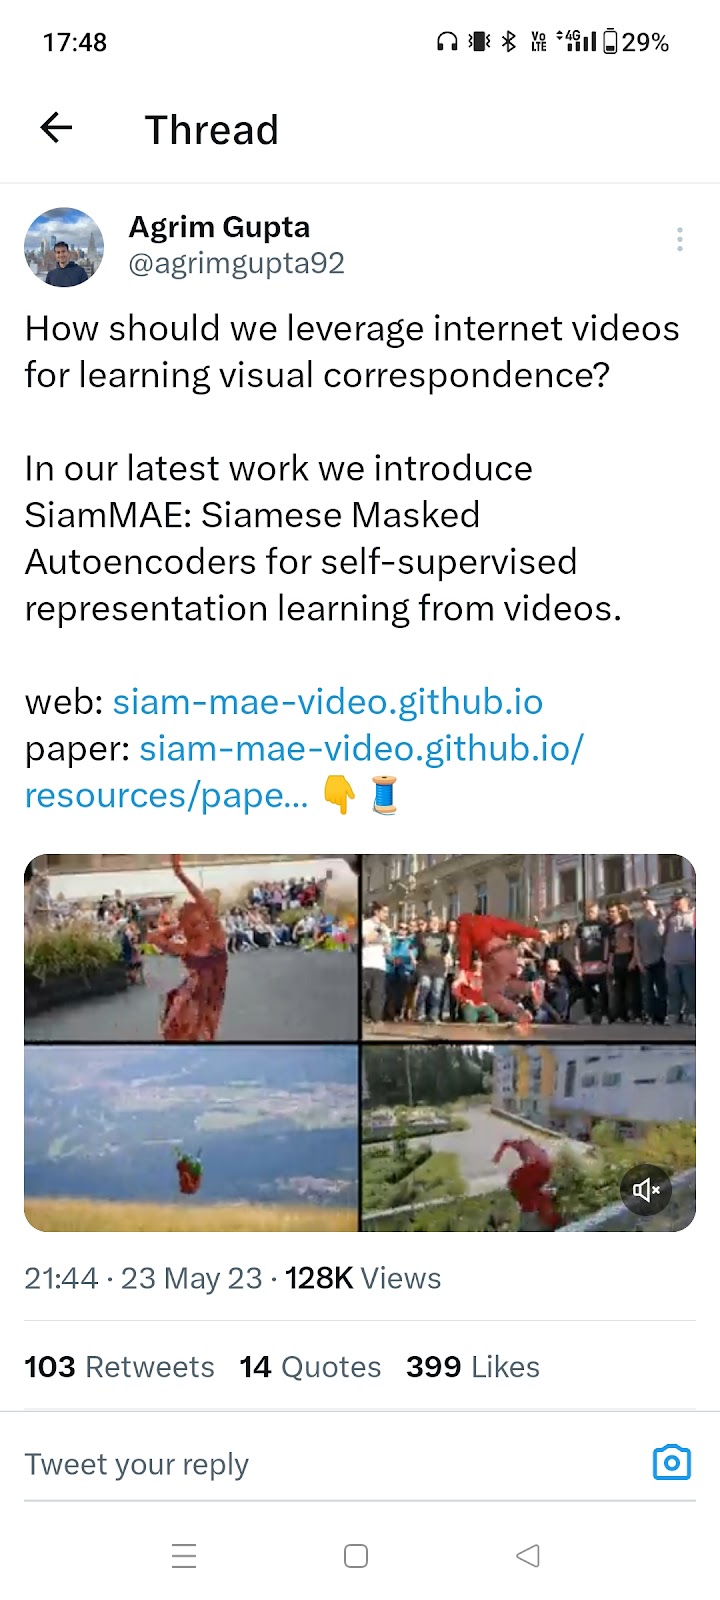
SiamMAE: Siamese Masked Autoencoders for self-supervised representation learning from videos #1123

Image
SiamMAE: Siamese Masked Autoencoders for self-supervised representation learning from videos #1123 Source

Introducing #ClinicalCamel 🐪: an innovative open-source conversational #LLM engineered specifically for healthcare #1122

Image
Introducing #ClinicalCamel 🐪: an innovative open-source conversational #LLM engineered specifically for healthcare #1122 Source  

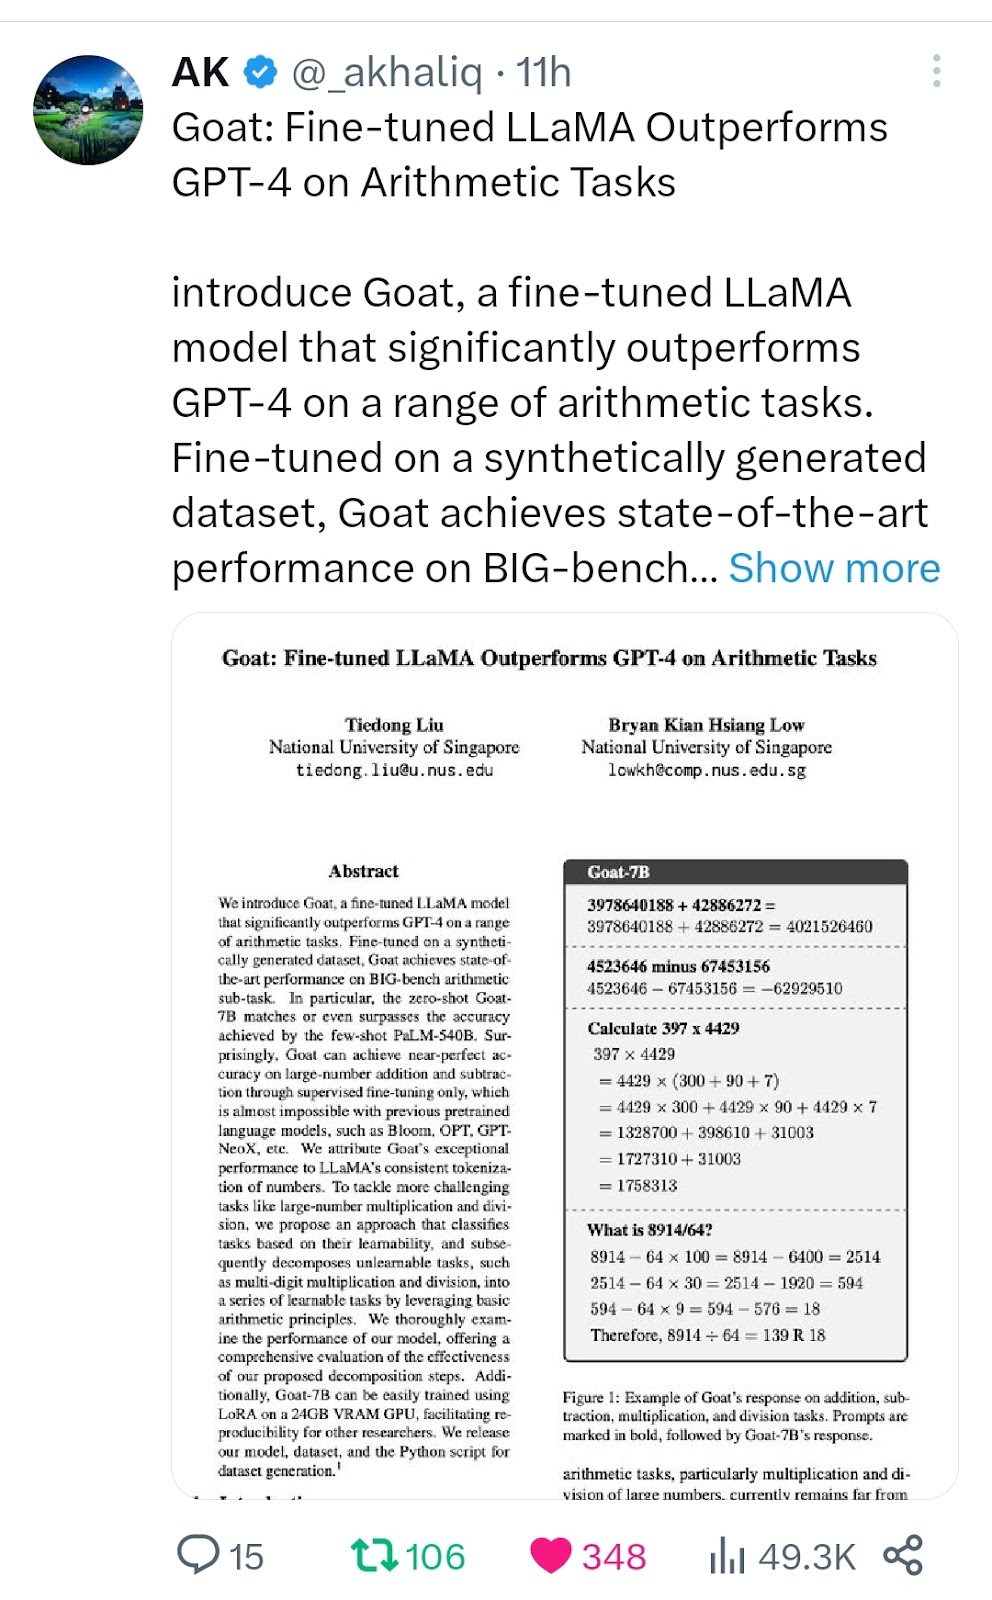
Goat: Fine-tuned LLaMA Outperforms GPT-4 on Arithmetic Tasks #1121

Image
Goat: Fine-tuned LLaMA Outperforms GPT-4 on Arithmetic Tasks #1121 Source  

QLoRA: Efficient Finetuning of Quantized LLMs #1120

Image
QLoRA: Efficient Finetuning of Quantized LLMs #1120 Source

Enhancing Detail Preservation for Customized Text-to-Image Generation: A Regularization-Free Approach #1119

Image
Enhancing Detail Preservation for Customized Text-to-Image Generation: A Regularization-Free Approach #1119 Source  

Control-A-Video: Controllable Text-to-Video Generation with Diffusion Models #1118

Image
Control-A-Video: Controllable Text-to-Video Generation with Diffusion Models #1118 Source  

Introducing Microsoft Fabric: Data analytics for the era of AI #1117

Image
Introducing Microsoft Fabric: Data analytics for the era of AI #1117 Source

Intel Announces Aurora genAI, Generative AI Model With 1 Trillion Parameters #1116

Image
Intel Announces Aurora genAI, Generative AI Model With 1 Trillion Parameters #1116 Source  

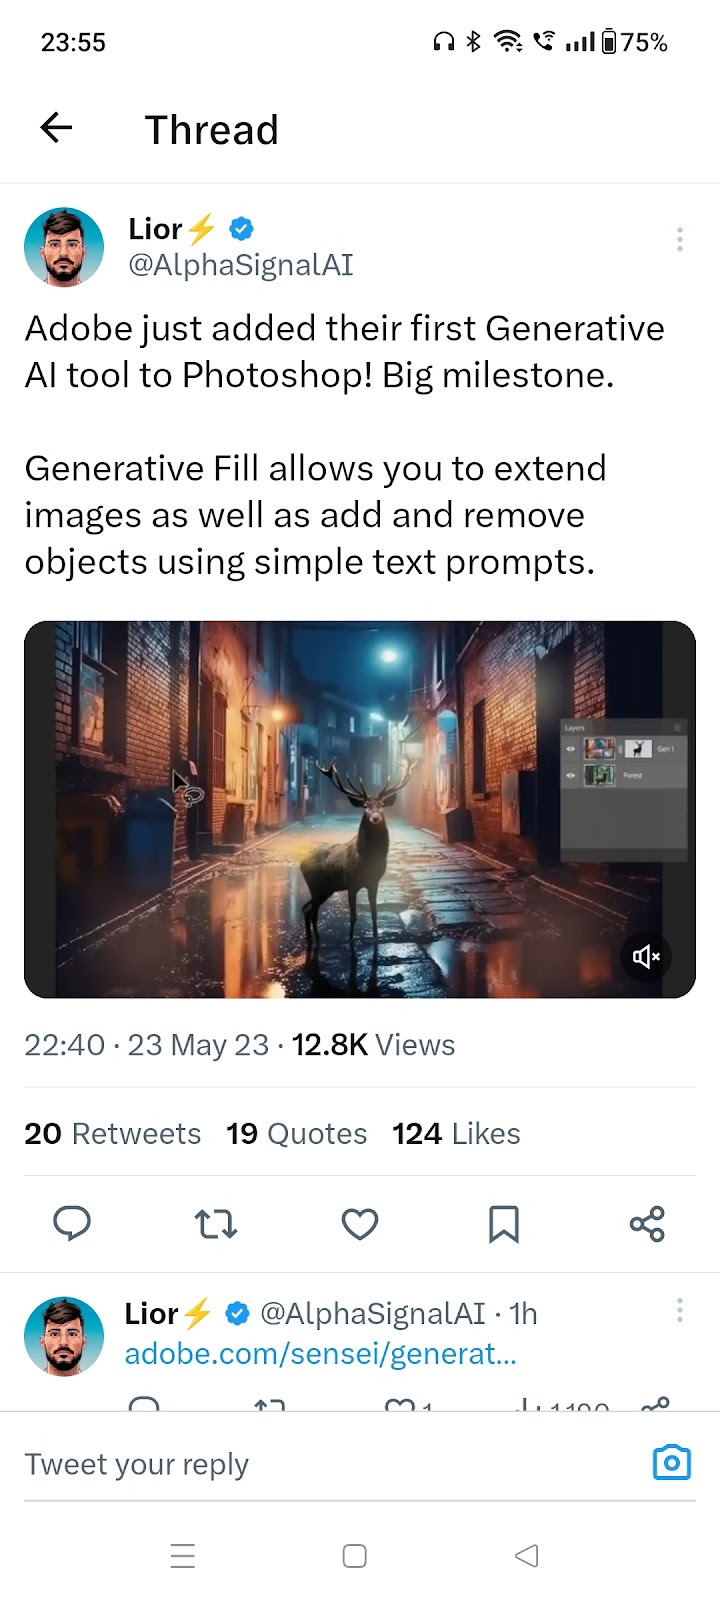
Adobe just added their first Generative AI tool to Photoshop #1115

Image
Adobe just added their first Generative AI tool to Photoshop #1115 Source

Google introduces Product Studio, a tool that lets merchants create product imagery using generative AI #1114

Image
Google introduces Product Studio, a tool that lets merchants create product imagery using generative AI #1114 Source  

Announcing, Windows Copilot. Integrating the power of Bing Chat across all of Windows and all your apps #1113

Image
Announcing, Windows Copilot. Integrating the power of Bing Chat across all of Windows and all your apps #1113 Source  

Meta's MMS: Massively Multilingual Speech - Can do speech2text and text speech in 1100 languages #1112

Image
Meta's MMS: Massively Multilingual Speech - Can do speech2text and text speech in 1100 languages #1112 Source